Theia
A model that reads fashion photographs.
A model that reads fashion photographs.
Benchmarks
The share of photos each AI got right, on four tests. Longer bar is better. When an AI said “I don’t know”, that counted as wrong.
Not every AI was run on every test, so some bars are missing. Theia leads three of the four tests. Claude Opus 5.5 leads exact product names.
Each dot is one AI on the runway photos. Up and to the left is better: more right, for less money. Pick a score to see how the picture changes.
Cost per photo in US dollars, on a log scale (each step is about 2 to 3 times more). Measured from the runs.
The model
Mission
We are building an AI that understands fashion from the ground up.
Theia is the first step toward the ultimate ArchiveAgent: an AI designed for fashion.
House, season and year: 287 new runway photos. Exact product: 75 products, a different and harder test.
How we tested
Fresh photosTheia never trained on any test photo, show or product. We checked every file.
The same question for every AIEvery AI got the same photos and the same instructions, through OpenRouter. Theia ran on Tinker.
No credit for “I don’t know”A pass, or an answer that ran out of room, counts as wrong.
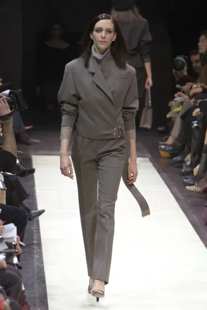
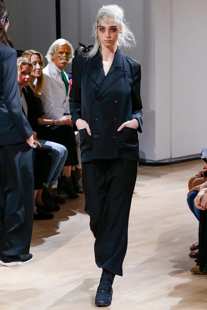
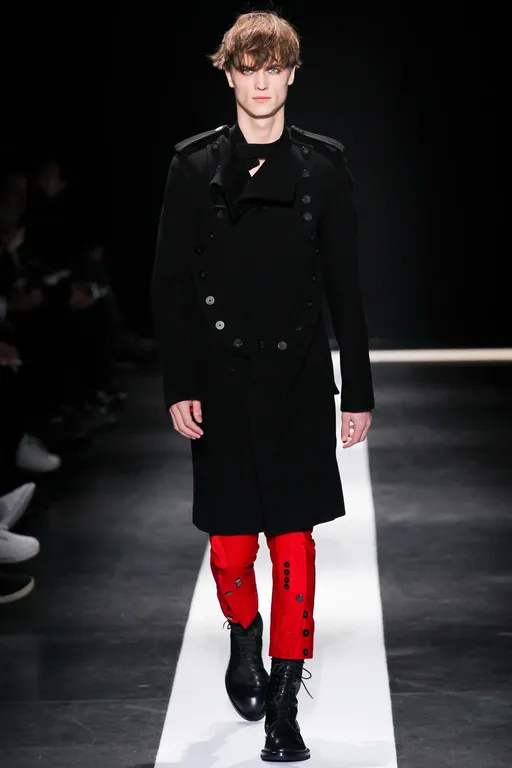
287 runway photos from 41 shows that were kept out of Theia’s training. House, season and year all had to be right.
The question
Which house, season and year is this look from?
The right answer
Ann Demeulemeester, Fall/Winter, 2015
What each AI said
All three parts must be right to score. “I don’t know” counts as wrong.
Many of them said “I don’t know.” That counts as wrong. Theia was trained to always make its best guess.
12%to56%
Kimi K2.6, the AI we started from, then Theia after our extra lessons.
In shortTheia got 56% fully right. The next best, Kimi K3, got 45%. Claude Opus 5.5 got 29%.
150 product photos from three houses: Louis Vuitton, Chanel and Rick Owens. The only job: name the house.
Three of the 150 product questions, one per house, picked at random (not by how well anyone did).
5 photos of this item. Tap one to look through them all.
The question
Here are photos of one item. Which house made it?
The right answer
Louis Vuitton
What each AI said
A decline does not count. A collaboration, like “Louis Vuitton x Nike”, counts as naming the house.
5 photos of this item. Tap one to look through them all.
The question
Here are photos of one item. Which house made it?
The right answer
Chanel
What each AI said
A decline does not count. A collaboration, like “Louis Vuitton x Nike”, counts as naming the house.
5 photos of this item. Tap one to look through them all.
The question
Here are photos of one item. Which house made it?
The right answer
Rick Owens
What each AI said
A decline does not count. A collaboration, like “Louis Vuitton x Nike”, counts as naming the house.
In shortTheia got all 150. Claude Opus 5.5 got 148. That is too close to call. Gemini 3.1 Pro, which often did not answer, got 55%.
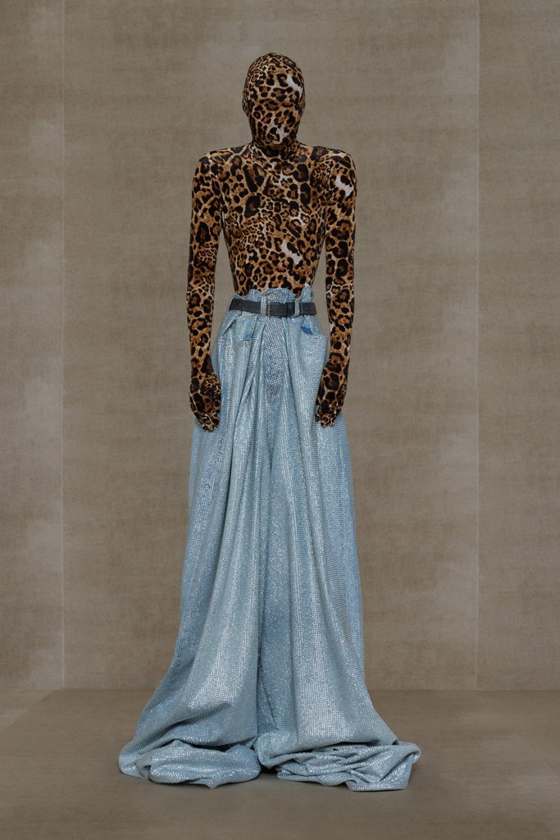
A second, smaller runway test: 50 looks from shows kept completely out of training.
The question
Which house, season and year is this look from?
The right answer
Vetements, Spring/Summer, 2024
What each AI said
Same scoring as the Runway Test: all three must be right.
In shortTheia got 28 of 50. The best of the others got 13. With only 50 photos, treat this as a second opinion, not proof.
The hardest one. Up to six photos of one product, and the AI must name it exactly, like “Christopher MM backpack.” A second AI judges whether the name matches.
Example 1 shows how the judge works. Examples 2 and 3 were picked at random from the 75 products.
6 photos of this item. Tap one to look through them all.
The question
Here are up to six photos of one item. What exactly is it?
The right answer
Louis Vuitton Christopher MM backpack
What each AI said
A second AI checks whether each answer is the same product as the right answer. Theia said “PM” where the answer is MM, so it is marked wrong.
6 photos of this item. Tap one to look through them all.
The question
Here are up to six photos of one item. What exactly is it?
The right answer
Louis Vuitton LV Trainer low-top sneaker in black/gray Monogram denim
What each AI said
A second AI checks whether each answer is the same product as the right answer.
6 photos of this item. Tap one to look through them all.
The question
Here are up to six photos of one item. What exactly is it?
The right answer
Rick Owens Knee Pull On Gabe
What each AI said
A second AI checks whether each answer is the same product as the right answer.
The name is not in the photoA brand can invent a name, like Gemini Bag. The AI has to have learned it.
Look-alikesA brand sells many similar bags and boots, each with its own name.
Close is wrongThe right kind of item with the wrong name does not score.
Long descriptions7 or more words, like “black leather jacket with zip pockets” · 27 products
Short phrases4 to 6 words · 25 products
Made-up model names1 to 3 words, like “Gemini Bag” · 23 products
Every AI does fine when the right answer is a long description. The score drops when it is a short, made-up model name. That is the hardest slice: 23 of the 75 products. On it, Theia got 9 of 23, Claude Opus 5.5 8 and GPT-6.1 Sol 6. Two real cases:
6 photos of this item. Tap one to look through them all.
The question
Which exact product is this?
The right answer
Rick Owens Gemini Bag
What each AI said
Rick Owens calls this bag “Gemini”. That is a name to learn, not something you can read off the photo.
6 photos of this item. Tap one to look through them all.
The question
Which exact product is this?
The right answer
Rick Owens Meganaska
What each AI said
“Meganaska” and “Cargotaconaska” are two different Rick Owens boots in our data. Close is not enough.
A caution. Of those 23, 17 are from product lines that also appear in our training photos, and 6 are from lines Theia never saw. On the 17, Theia got 8, Opus 7 and Sol 5. On the 6, each got 1, 1 and 1. So part of Theia’s skill here is remembering lines it was shown. We have not yet tested with whole lines held out.
In shortThis is where Theia does not win. Claude Opus 5.5 named 59% of the products and Theia 51%. With only 75 products, a gap this size could be luck.
Who won what
One point to the winner of each contest. It counts contests; it is not one grand score.
Cost
Training Theia cost $18.35, one time. After that, naming a photo costs about 0.14 cents.
In short. For each photo it gets fully right, Theia costs about 17 times less than Claude Opus 5.5. The $18.35 of training pays for itself after roughly 1,700 photos. We count the photos it gets wrong too, because you pay for those.
The build
We did not build an AI from nothing. We took an open one, Kimi K2.6, and taught it fashion.
Build the testFresh photos Theia never trained on. We checked: none are shared.
Write the rules firstThe scoring rules were written down, dated and hashed before any run.
Same test for allOne script, the same photos, the same question, every AI through OpenRouter.
Teach it5,025 examples, one pass, 80 minutes.
Check our own workWe found three mistakes of our own, fixed them, and say so below.
ArchiveAgent and Theia are not affiliated with or endorsed by Moonshot AI or Thinking Machines. Kimi K2.6 is released under a modified MIT licence.
Honest notes
At a glance
| Theia | Claude Opus 5.5 | GPT-6.1 Sol | Gemini 3.1 Pro | Claude Sonnet 5.5 | Grok 4.7 | Kimi K3 | Kimi K2.6 | Qwen3.5-397B | |
|---|---|---|---|---|---|---|---|---|---|
| Runway: house287 photos | 87.8% | 74.2% | 66.2% | 49.5% | 59.2% | 32.1% | 61.0% | 52.6% | 33.8% |
| Runway: season287 photos | 85.7% | 60.6% | 56.4% | 52.6% | 47.0% | 8.7% | 59.2% | 16.7% | 48.8% |
| Runway: year287 photos | 64.1% | 30.3% | 30.0% | 30.0% | 23.0% | 1.4% | 48.1% | 12.2% | 18.1% |
| Runway: all three287 photos | 56.4% | 28.6% | 26.1% | 23.0% | 21.6% | 1.4% | 44.9% | 12.2% | 5.2% |
| Product photos: house150 cases | 100.0% | 98.7% | 95.3% | 55.3% | 92.7% | 20.7% | — | — | — |
| Blind runway: all three50 photos | 56.0% | 22.0% | 20.0% | 26.0% | 22.0% | 0.0% | — | — | — |
| Exact product75 products | 50.7% | 58.7% | 52.0% | — | — | — | — | — | — |
| Cost per photoUSD, measured | $0.0014 | $0.0124 | $0.0051 | $0.0061 | $0.0059 | $0.0075 | $0.0067 | $0.0005 | $0.0006 |
Runway rows: 287 new photos from 41 shows; house, season and year scored exactly (pre-fall and resort count as their own seasons). Product house: 150 cases; a collaboration answer such as “Louis Vuitton x Nike” counts as naming the house. Blind runway: 50 photos. Exact product: 75 products, same prompt for every AI, a second AI judges; only three systems were run on it. Every comparison AI ran through OpenRouter with the same instructions; Theia ran on Tinker. Those instructions say abstaining is better than guessing, which some AIs follow more than others; a decline counts as wrong. Costs are measured per photo from the runs. One run per system; labels are model-made and trusted by the owner.